B.Tech Data Science Student | Data Engineer | AI/ML Developer
Creator of Stock Market Future — AI-powered quantitative financial intelligence platform. I build end-to-end data pipelines, optimize relational databases, deploy scalable AI/ML solutions, and construct interactive full-stack applications.
Featured Credentials
100% Coding • Certified SE
Infosys Springboard
IBM SkillsBuild
HP LIFE
class DataScientist:
    def __init__(self):
        self.name = "Krishna Gupta"
        self.role = "Data & AI Developer"
        self.education = "B.Tech Data Science (2027)"
        self.skills = [
            "Python", "PySpark", "SQL",
            "AI/ML", "RAG", "LLMs"
        ]

    def objective(self):
        return "Build scalable AI & Data systems"

me = DataScientist()
print(me.objective())I am an AI/ML Engineer and B.Tech in Data Science student (Class of 2027) at the Oriental Institute of Science and Technology, Bhopal. I have dual industry internship experience architecting Large Language Model (LLM) post-training workflows, autonomous multi-agent systems (LangGraph), and high-throughput data pipelines.
My proven expertise spans the entire MLflow lifecycle (tracing, model evaluation, prompt templates, AI gateways, agent servers, and hyperparameter tuning), computer vision & OCR (OpenCV, EasyOCR), and full-stack cloud microservices maintaining 99.9% uptime. Certified AWS Developer with deep technical proficiency in PyTorch, Scikit-learn, FastAPI, and SQL database optimization.
Architecting autonomous multi-agent operating systems (LangGraph), Vision-Language Models (VLMs), and Hybrid RAG pipelines cutting query latency by 40%.
End-to-end MLflow tracing, model evaluation, prompt templates, AI gateways, agent servers, and systematic hyperparameter tuning.
Building high-accuracy OCR extraction and semantic vector matching engines with OpenCV, EasyOCR, and FAISS achieving sub-200ms latency.
Deploying production-grade FastAPI microservices, React.js apps, Docker containers, and optimizing PostgreSQL/MySQL schemas with 99.9% uptime.
Architecting autonomous multi-agent systems and multi-step reasoning workflows with graph-based orchestrators and tool-calling servers.
Benchmarking 50,000+ model outputs, LLMOps alignment (RLHF/DPO), prompt templates, safety guardrails, and Vision-Language models.
Constructing high-throughput semantic retrieval systems combining dense vector embeddings with ultra-fast vector index engines.
Full lifecycle tracking: request tracing, automated evaluation matrices, prompt template registries, and AI gateway proxy servers.
Systematic hyperparameter optimization, model registry versioning, artifact caching, and PyTorch/Scikit-Learn experiment management.
Continuous integration, Docker containerization, AWS cloud architecture, and high-availability server administration maintaining 99.9% uptime.
Supervised and unsupervised learning, advanced classification, predictive regression, clustering, and data dimensionality reduction.
Convolutional neural networks (CNNs), deep feature extractors, optical character recognition (OCR), and sub-200ms image matching.
Quantitative financial asset modeling and LSTM recurrent networks predicting asset price movements with 88% precision.
Developing high-performance RESTful APIs, asynchronous microservices, resilient distributed architectures, and modern web backends.
Optimizing relational schemas, indexing strategies, sub-second query latency, and designing dimensional Star and Snowflake schemas.
Constructing high-reliability ETL/ELT pipelines, real-time transaction webhook recovery, Git version control, and Linux sysadmin.
6-Month AI Engineer Program
Paid Internship
Paid Internship
Engineered an autonomous multi-agent operating system integrating LLMs and Vision-Language Models (VLMs) via LangGraph & LangChain. Constructed a low-latency Hybrid RAG pipeline with FAISS cutting retrieval latency by 40%, plus integrated MLflow tracing, prompt evaluation templates, and automated guardrail logging.
Developed an intelligent OCR and computer vision pipeline achieving 92% text extraction accuracy and sub-200ms semantic matching on complex imagery. Integrated Sentence-Transformers and FAISS vector databases to construct a semantic matching and ETL transformation service deployed with FastAPI.
Constructed an automated transaction recovery pipeline capturing failed payment webhooks in real time, successfully recovering 18% of abandoned checkouts. Designed analytical SQL schemas in PostgreSQL to aggregate transaction failure patterns, automate notification triggers, and generate recovery analytics.
Engineered an image-to-text OCR and semantic book-matching platform using EasyOCR and FAISS vector search, achieving sub-200ms query retrieval latency across high-density book collections and physical libraries.
Built a quantitative time-series forecasting model using PyTorch (LSTM) and Scikit-learn to predict financial asset price trends with 88% precision. Implemented MLflow hyperparameter tuning and experiment tracking to systematically evaluate learning rates, sequence lengths, and optimizer parameters.
Architected and deployed full-stack web infrastructure for review analytics platform "RevU Social" using React.js and Node.js REST APIs, driving a 20% user increase. Designed dimensional star-schema database models in PostgreSQL/MySQL to power real-time business intelligence and performance dashboards.
Engineered an AI-powered GovTech intelligence platform empowering Indian entrepreneurs to match with government schemes, subsidies, and credit-linked incentives. Features a multilingual conversational mentor (NITI Saathi AI), rule-based eligibility evaluation, and sub-100ms edge delivery with Next.js 14 and Cloudflare Workers.
Browse and verify official credentials, cloud certifications, and technical completions.
Scored 611/800 (“Excellent”) ranking in the 97th National Percentile (98th Regional). Achieved 100% Score in Coding (5/5) and 87% in Computer Fundamentals (5/5) with certified High Job Suitability for Software Engineer roles.
Validates technical proficiency in core AWS services, containerized microservices deployments, IAM policies, and serverless architectures.
Completed ML0101EN focusing on predictive regression, classification algorithms, hierarchical clustering, and recommender systems with Python.
Statistical analysis, exploratory data analysis (EDA), data extraction pipelines, and applying business intelligence metrics for strategic decision-making.
Deep learning foundations, multi-layer perceptrons, backpropagation, convolutional layers (CNNs), feature map pooling, and image processing architectures.
Practical data analysis simulation analyzing client datasets, forensic data investigation, statistical trend identification, and executive dashboard communication.
Business intelligence visualization simulation designing executive dashboards, exploratory data analysis, and translating complex operational metrics for leadership.
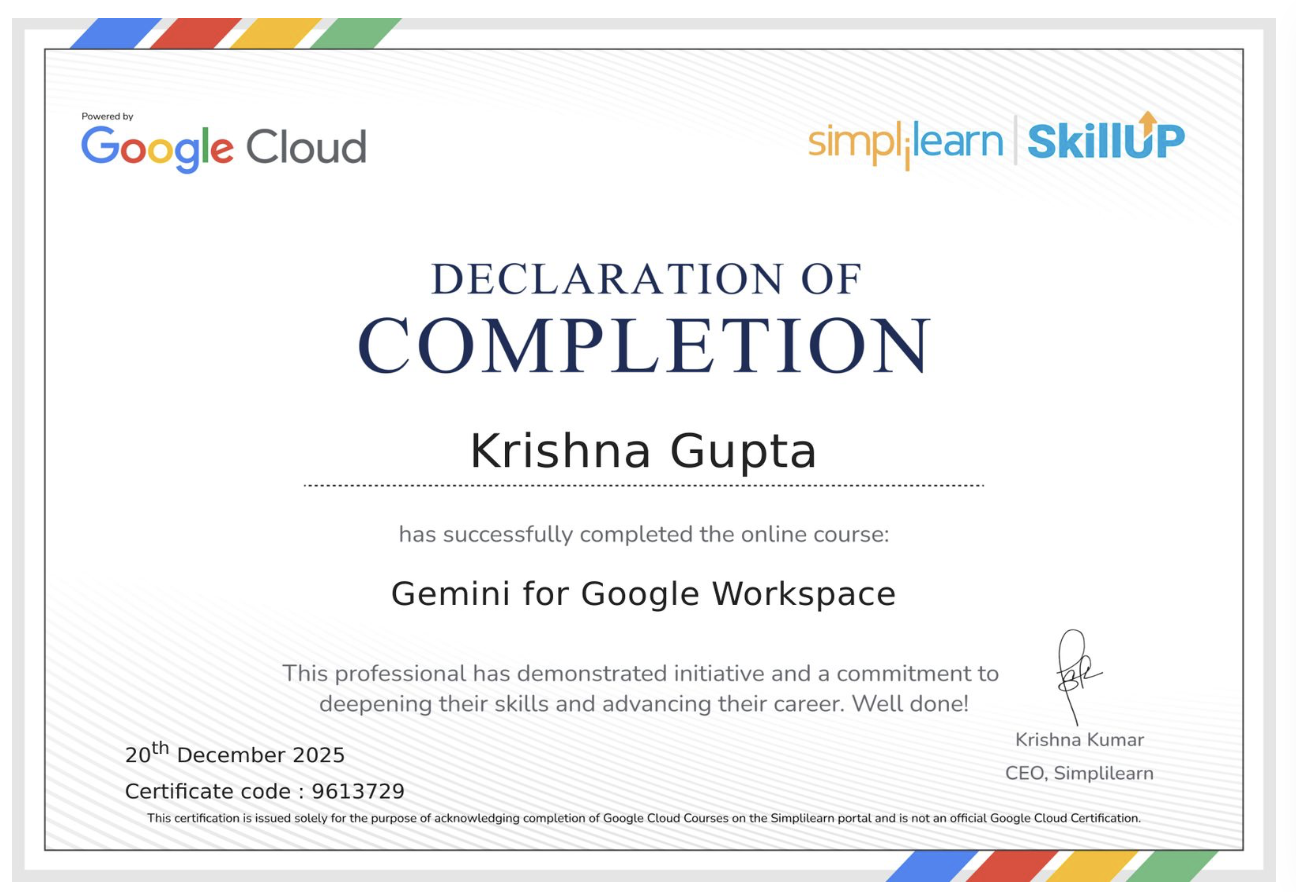
Practical implementation of generative AI workflows, prompt design, and AI-driven productivity systems.
Advanced relational querying, joins, indexing strategies, data aggregation, and database schema administration.
Competitive coding challenges, in-person AI agent hackathons, and national industry recognitions.
Selected as a verified Participant in HackerRank Orchestrate – October Edition 2026, a competitive coding and AI orchestration challenge focused on algorithm design, API development, and intelligent workflow automation.
Participated in an in-person AI agent hackathon in Bengaluru – built governed, automated agentic workflows using LLMs, multi-agent frameworks, and autonomous orchestration pipelines.
Completed the national Full Stack Web Development Challenge 2026 – assessed and certified on full-stack microservices architecture, REST API design, and modern web engineering best practices.
Recognized as Star Performer among all cohort participants in the AICTE-sanctioned Oasis Infobyte SIP (OIB/M1/IP301) – awarded for exceptional dedication and outstanding contributions in Data Science.
Completed the Nestlé E-learning 2026 | Resilience module as part of the Nesternship – a globally recognized corporate learning initiative for emerging engineering leaders.
Selected as SDE Intern at Bluestock Fintech – contributed to software engineering in a dynamic fintech environment, gaining hands-on experience with real-world financial software pipelines.
97th National Percentile | Score: 611/800 (“Excellent”)
100% Score in Coding (5/5) • 87% in Computer Fundamentals (5/5) • 98th Regional Percentile • Certified High Job Suitability for Software Developer & Software Engineer roles.
Bachelor of Technology (B.Tech) in Data Science (Class of 2027)
Focusing on algorithms, advanced data schemas, data warehousing, high-throughput pipelines, and AI/ML modeling.
Higher Secondary Education (Class X & XII)
Strengthened analytical capabilities in Mathematics, Physics, and Computer Science.
I am actively seeking internships, entry-level, or remote roles in Data Engineering, AI/ML development, and Software Engineering.
Bhopal, Madhya Pradesh, India (Open to remote & relocation)